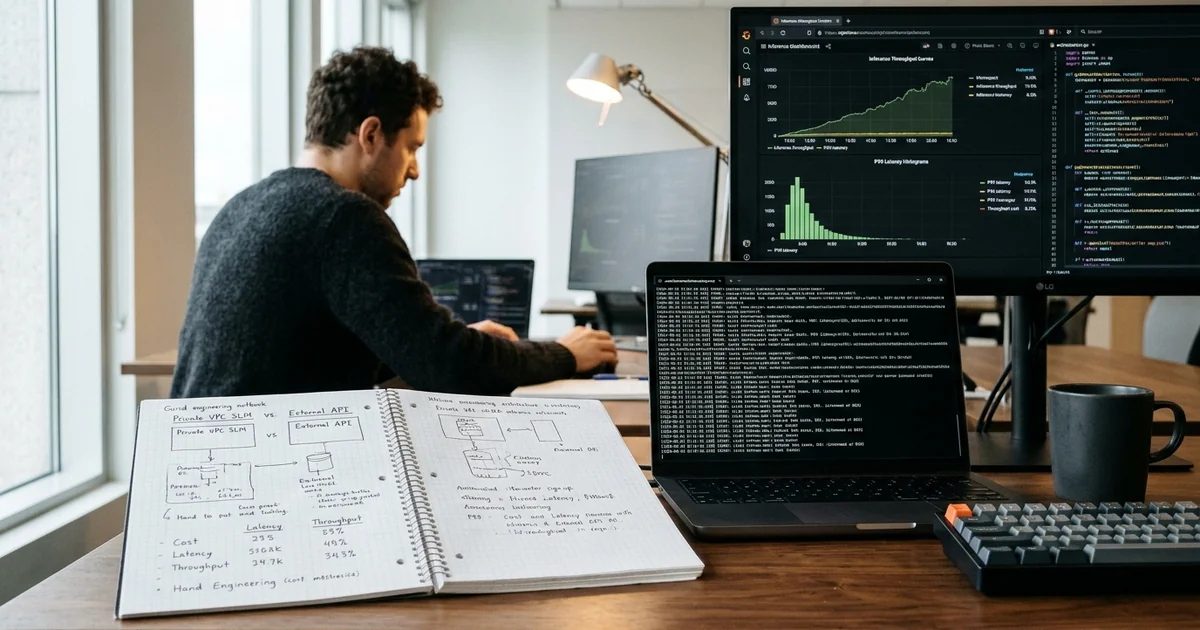
Evaluating self-hosted SLMs vs enterprise LLM APIs determines how organizations balance data sovereignty, predictable unit economics, and P99 tail latency in production software. Self-hosted small language models (1B to 14B parameters) execute inside an enterprise virtual private cloud (VPC) with zero external data egress, whereas commercial frontier APIs prioritize broad zero-shot reasoning on a per-token billing model.
As software organizations and digital agencies move from isolated chatbots into regulated production workflows across healthcare, fintech, and client portals, routing raw customer records to third-party endpoints creates acute compliance and cost bottlenecks. Engineering leaders must decide when private open-weight deployments justify dedicated GPU infrastructure and when commercial APIs remain the faster, cheaper choice. Our earlier overview of creating artificial intelligence and leveraging machine learning and our guide to enterprise AI workflow automation established the core pipeline layers; below is the architectural framework for selecting the right inference tier.
Key Takeaways for Technology Leaders
- Zero External Data Egress: Self-hosted small language models (1B–14B parameters) run inside private VPCs or on-premises clusters, eliminating third-party data transfer risks under GDPR, HIPAA, and strict agency NDAs.
- The 15M–20M Token Monthly Breakeven: Below ~15 million tokens per month or during spiky traffic, pay-per-token commercial APIs win financially; above steady high-volume thresholds, dedicated GPU inference cuts effective token costs by 60% to 90%.
- Deterministic P99 Tail Latency: Optimized serving engines running vLLM with PagedAttention keep Time-to-First-Token (TTFT) under 35ms inside corporate networks, avoiding multi-second cloud API rate-limit queues.
- Hybrid Tiered Routing Dominates Production: Mature enterprise systems pair fine-tuned SLMs for 80% of repetitive classification, extraction, and routing workloads with commercial frontier APIs reserved for complex open-ended synthesis.
Why Comparing Self-Hosted SLMs vs Enterprise LLM APIs Matters in 2026
Early enterprise AI integrations defaulted almost exclusively to commercial frontier APIs because initial prototypes prioritized rapid iteration over unit economics or compliance isolation. Once those features hit production traffic across internal ERPs, patient intake portals, and customer support pipelines, three structural pressures quickly emerge: escalating monthly token invoices, unpredictable P99 latency spikes during shared cloud peaks, and strict legal scrutiny over external data processing.
Modern open-weight small language models—ranging from 1B to 14B parameters across families such as Llama, Phi, Gemma, and Qwen—have closed the accuracy gap on structured enterprise tasks. When paired with retrieval-augmented generation (RAG) or lightweight parameter-efficient fine-tuning (LoRA), compact models routinely match or outperform massive generalist APIs on narrow workflows like PII redaction, invoice parsing, SQL generation, and intent routing.
Data Privacy, Sovereignty, and Regulatory Compliance (GDPR, HIPAA & EU AI Act)
For CTOs and digital agencies delivering software under strict non-disclosure agreements (NDAs), data governance is frequently the deciding architectural constraint rather than raw benchmark scores.
Data Residency, Cross-Border Transfers, and GDPR Article 25
Although major commercial LLM API vendors offer zero-data-retention enterprise tiers and regional endpoints, sending raw customer records across external network boundaries still requires complex Data Processing Agreements (DPAs), vendor sub-processor audits, and cross-border transfer reviews under GDPR Regulation (EU) 2016/679. Under GDPR Article 25 (Data Protection by Design and by Default), organizations must minimize exposure of personal data.
Running a self-hosted SLM inside an isolated Virtual Private Cloud (VPC) eliminates third-party transmission entirely. Prompts, embeddings, and intermediate logs never leave the enterprise security perimeter, simplifying Business Associate Agreement (BAA) scoping for HIPAA-regulated healthcare workflows and satisfying strict client confidentiality clauses in white-label agency software development.
GDPR Article 17 Erasure and EU AI Act Auditability
Two compliance obligations disproportionately favor self-hosted SLMs coupled with clean RAG stores over opaque external models:
- Right to Erasure (GDPR Article 17): When customer knowledge lives in a controlled internal vector database rather than being baked into external model weights, deleting a customer’s records immediately removes their footprint without re-negotiating vendor retention cycles.
- Reproducibility and Transparency ([EU AI Act Regulation 2024/1689](https://eur-lex.europa.eu/eli/reg/2024/1689/oj)): Commercial API checkpoints evolve silently behind provider routing endpoints, which can shift classification behavior overnight. Self-hosted SLMs freeze exact model weights, quantization levels, and deterministic decoding seeds inside versioned container images.
| Security Rule: Even when deploying private VPC models, treat every prompt and retrieval payload against the OWASP Top 10 for LLM Applications. Physical network isolation prevents external data leaks, but you still require input sanitization, schema bounds, and role-based access control to block indirect prompt injection. |
Latency Budgets, Throughput, and Serving Infrastructure
Interactive enterprise portals, voice triage bots, and live financial dashboards break down when inference latency swings wildly. Commercial frontier APIs traverse public internet gateways and multi-tenant vendor queues, causing P99 tail latency to spike between 1,200ms and 4,000ms+ under peak load alongside hard tokens-per-minute (TPM) rate limits.
By contrast, quantized 4B–8B models served inside the same cloud region via vLLM PagedAttention with continuous batching regularly achieve Time-to-First-Token (TTFT) under 15ms–35ms. Because compute capacity belongs strictly to your cluster, predictable throughput scales horizontally with replica autoscaling rather than hitting external API throttling errors.
When Commercial LLM APIs Still Win
Self-hosting is not universally optimal. Maintaining dedicated GPU nodes introduces MLOps responsibilities: container patching, cold-start tuning, KV-cache memory profiling, and model evaluation regression testing. Commercial APIs remain superior when:
- Traffic Is Low or Highly Spiky: An idle GPU instance burns cloud budget 24/7. Below ~15 million tokens per month or for sporadic batch jobs, pay-per-token APIs eliminate idle hardware waste.
- Workloads Require Broad Multi-Step Synthesis: Complex cross-domain reasoning, massive 200K+ token context ingestion, and ambiguous creative analysis still benefit from frontier parameter scale.
- Rapid MVP Validation: During early product discovery—outlined in our guide on writing effective product requirements documents and our review of generative AI vs traditional rendering—commercial APIs let product teams ship in days without provisioning GPU clusters.
Self-Hosted Private SLMs vs. Commercial Enterprise LLM APIs
| Architectural Dimension | Commercial Enterprise LLM APIs | Self-Hosted Private VPC SLMs | Hybrid Tiered Routing (Recommended) |
| Data Residency & Egress | Data transits external vendor endpoints; relies on DPA and zero-retention policies. | Zero external egress; prompts and weights remain inside corporate VPC. | Sensitive PII/PHI stays on local SLMs; anonymized reasoning escalates selectively. |
| GDPR / HIPAA Compliance | Requires vendor BAA, regional pinning, and sub-processor legal audits. | Simplifies GDPR Art. 17/25 and HIPAA isolation via physical control. | Strict policy router blocks unmasked PII from leaving the local boundary. |
| Economic Scaling Model | Zero fixed idle cost; scales linearly per million input/output tokens. | Fixed GPU instance cost; lowers high-volume cost by 60%–90% at >10% utilization. | Minimizes GPU footprint while avoiding frontier token bill shock. |
| P99 Tail Latency | Variable (1,000ms–4,000ms+ spikes during shared cloud peaks and rate limits). | Predictable (<35ms TTFT inside local VPC using vLLM continuous batching). | Sub-50ms responses on routine workflows; higher latency confined to deep tasks. |
| Model Deterministic Control | Subject to silent provider checkpoint updates and deprecation schedules. | Pinned weights, fixed quantization, and reproducible CI/CD eval parity. | Deterministic local routing rules paired with versioned API fallbacks. |
| General Reasoning Ceiling | Highest capability on novel, multi-hop synthesis and 200K+ token windows. | Strong on narrow extraction, classification, and tool formatting after tuning. | Matches task complexity directly to the lowest-cost capable model tier. |
| DevOps & MLOps Overhead | Minimal; provider manages hardware, scaling, and inference runtimes. | Moderate to high; requires GPU provisioning, autoscaling, and telemetry. | Managed cleanly through unified OpenAI-compatible gateway interfaces. |
Real-World TCO Scenario & Four-Phase Hybrid Implementation Blueprint
Consider a B2B healthcare claims and compliance SaaS platform processing 60 million tokens per month across 120,000 structured document classifications, PII redactions, and complex medical policy appeals.
Option A — All-Commercial Frontier API: Routing all 60M tokens (45M input / 15M output) through a top-tier frontier API at blended enterprise rates ($3/1M input, $15/1M output) costs roughly $360/month in raw baseline or $1,800–$3,500+/month once high-context system prompts, multi-turn retries, and premium reasoning models are included—while requiring strict BAA scoping on every payload.
Option B — Dedicated Always-On Self-Hosted SLM Cluster: Hosting an 8B quantized model via vLLM on a single dedicated L4/A10G GPU instance costs approximately $550–$850/month fixed, achieving <30ms TTFT and zero external PHI exposure. However, complex multi-document policy appeals still underperform compared to frontier reasoning.
Option C — Governed Hybrid Router (CodeInPK Production Model): A local PII scrubber and fine-tuned 8B SLM running in the client VPC handles 88% of traffic (52.8M tokens of extraction, redaction, and routine classification) with zero external PHI transfer. Only redacted, de-identified complex appeals (12% of volume) route to the commercial frontier API. Monthly infrastructure plus API spend stabilizes near $780/month, cutting variable token spend by over 70% while keeping regulated patient identifiers strictly inside the VPC.
Four-Phase Engineering Blueprint:
1. Phase 1 — Traffic & PII Audit: Classify production prompts by sensitivity (PII/PHI/NDA), average context length, and latency SLA to isolate candidates for local execution.
2. Phase 2 — OpenAI-Compatible Gateway Abstraction: Deploy an internal model router (such as LiteLLM or a custom FastAPI proxy) so application code calls one standardized interface regardless of backend model.
3. Phase 3 — Benchmark & Quantize with vLLM: Evaluate 4-bit/8-bit quantized SLMs (Llama, Qwen, Phi) on golden regression datasets until schema validity exceeds 99% under structured JSON constraints.
4. Phase 4 — Enforce Privacy & Cost Telemetry: Track GPU utilization, P99 TTFT, fallback rates, and PII-filter triggers in Prometheus/Grafana before cutting over production traffic.
Frequently Asked Questions About self hosted SLMs vs enterprise LLM APIs
Q: When is it cheaper to self-host a Small Language Model instead of paying for a commercial LLM API?
Self-hosting generally becomes cheaper once steady inference traffic keeps a dedicated GPU instance above roughly 10% to 15% utilization—typically around 15 million to 25 million tokens per month depending on input/output ratios and GPU tier. Below that threshold or during erratic workloads, pay-per-token commercial APIs avoid paying for idle hardware.
Q: Do self-hosted SLMs automatically make an application GDPR and HIPAA compliant?
No model is compliant on its own, but hosting an SLM inside your private VPC removes external third-party data transfers, simplifies GDPR Article 25 data minimization, and streamlines HIPAA scoping. Organizations must still enforce encryption at rest and in transit, strict RBAC, audit logging, and GDPR Article 17 erasure pipelines across vector databases.
Q: Can an 8B parameter small language model match GPT-class APIs on enterprise workflows?
On open-ended reasoning across unfamiliar topics, no. However, on specialized operational tasks—such as structured JSON extraction, ticket classification, PII redaction, and domain-specific SQL generation—a compact 3B to 14B SLM paired with RAG or targeted LoRA fine-tuning routinely achieves parity with frontier APIs at much lower latency and cost.
Q: What is the best inference runtime for hosting private SLMs in production?
For multi-user production workloads on NVIDIA GPUs, vLLM (using PagedAttention and continuous batching) and TensorRT-LLM are industry standards because they maximize concurrent token throughput and keep P99 tail latency predictable. Simpler local tools like Ollama work well for developer sandboxes and single-user edge environments.
Q: How can a digital agency or startup adopt private SLMs without hiring an in-house MLOps team?
Teams can bridge the MLOps gap by partnering with specialized AI engineering squads like CodeInPK under strict NDA terms. Using standardized gateway wrappers and containerized vLLM deployments lets your product team integrate private AI endpoints rapidly without maintaining GPU infrastructure manually.
Deploy Private, Cost-Predictable AI Infrastructure with CodeInPK
Choosing between private VPC inference and commercial APIs is an architectural decision that directly shapes your compliance posture, gross margins, and application latency. At CodeInPK, our senior AI engineers and full-stack architects build custom AI systems and automated workflows engineered around strict data privacy, Pydantic schema guardrails, and predictable cloud unit economics.
With over 10 years of delivery experience and 150+ global client implementations, we support both direct enterprise teams through full-stack software and AI development and digital agencies seeking NDA-protected capacity via our white-label development partnership.
Ready to benchmark private SLM hosting or architect a hybrid AI gateway for your platform? Start with our [try our developers free for 2 weeks](https://codeinpk.com/#contact) risk-free trial to validate engineering velocity, code standards, and model latency before making a long-term commitment.
This architectural guide is authored by the senior systems consulting and AI engineering team at CodeInPK for CTOs, security leads, agency directors, and technical product managers.